|
Yuqing Lan I am a PhD candidate at NUDT, where I am advised by Professor Kai Xu, Professor Chenyang Zhu and Professor Yijie Wang. My PhD research focuses on 3D vision, embodied intelligence, vision foundation models, and 3D scene understanding. I am particularly interested in enabling machines to perceive, represent, and reason about complex real-world environments from visual observations. My works aim to bridge geometric perception and semantic understanding for more robust and generalizable embodied systems. |
|
ResearchI'm interested in 3D vision, embodied intelligence, and vision-language models. My research focuses on enabling machines to understand, represent, and reason about the physical world from visual observations. |
|
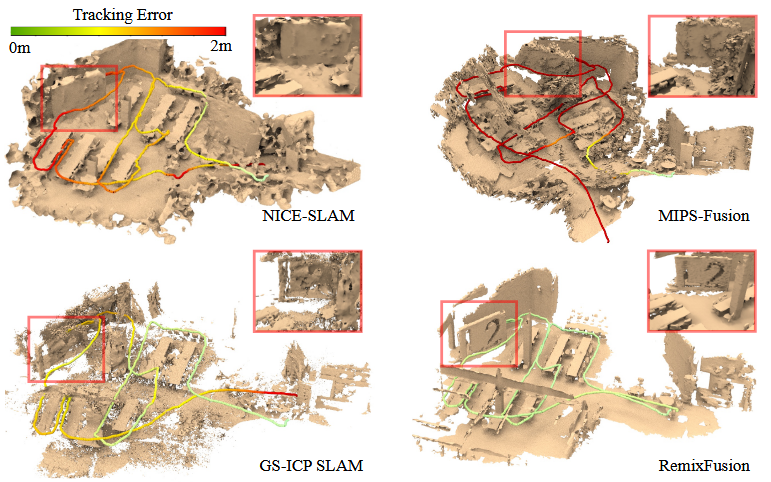
RemixFusion: Residual-based Mixed Representation for Large-scale Online RGB-D Reconstruction
Yuqing Lan, Chenyang Zhu, Shuaifeng Zhi, Jiazhao Zhang, Zhoufeng Wang, Renjiao Yi, Yijie Wang, Kai Xu ACM Transactions on Graphics (presented at SIGGRAPH ASIA 2025), 2025 Project page / Arxiv / Paper / Code RemixFusion is a residual-based mixed representation for scene reconstruction and camera pose estimation, dedicated to high-quality and large-scale online RGB-D reconstruction. |
|
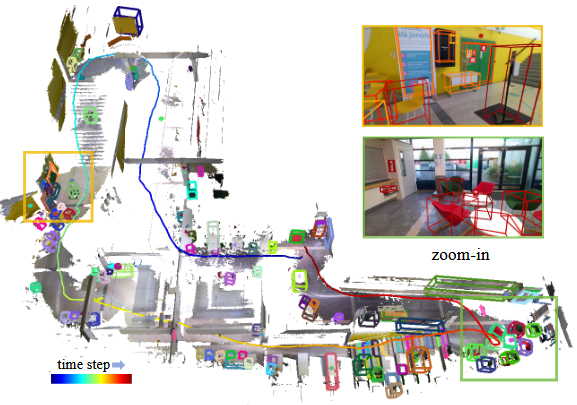
BoxFusion: Reconstruction-Free Open-Vocabulary 3D Object Detection via Real-Time Multi-View Box Fusion
Yuqing Lan, Chenyang Zhu, Zhirui Gao, Jiazhao Zhang, Yihan Cao, Renjiao Yi, Yijie Wang, Kai Xu Pacific Graphics (Journal Track), 2025 Project page / ArXiv / Paper / Code BoxFusion is a reconstruction-free online framework for open-vocabulary 3D object detection that fuses 2D detections from a pre-trained visual fundation model across multiple views into unified 3D boxes via correspondence matching and IoU-guided optimization. It enables real-time performance and achieves SOTA without needing expensive dense 3D reconstruction. |
|
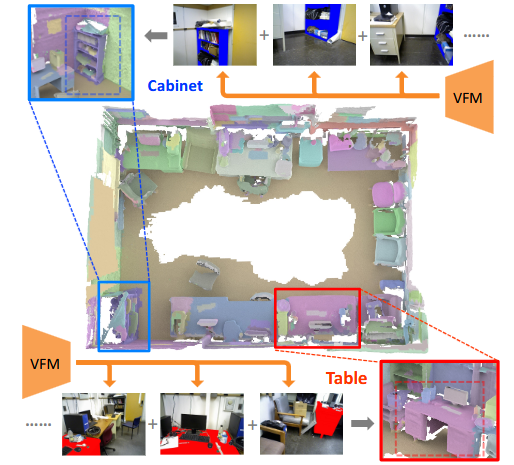
Onlineanyseg: Online zero-shot 3d segmentation by visual foundation model guided 2d mask merging
Yijie Tang, Jiazhao Zhang, Yuqing Lan, Yulan Guo, Dezun Dong, Chenyang Zhu, Kai Xu CVPR, 2025 Project page / ArXiv / Code To achieve online 3D open-vocabulary segmentation during real-time scene reconstruction, we propose a fast method of 2D masks lifting by using voxel hashing for efficient 3D scene querying. |
|
LLM-enhanced Scene Graph Learning for Household Rearrangement
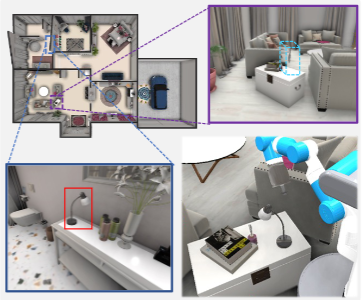
Wenhao Li, Zhinan Yu, Qijin She, Yuqing Lan, Chenyang Zhu, Ruizhen Hu, Kai Xu SIGGRAPH ASIA (Conference Track), 2024 Project Page / ArXiv We propose to mine object functionality with user preference alignment directly from the scene itself through LLM-enhanced scene graph learning which transforms the input scene graph into an affordance-enhanced graph with information-enhanced nodes and newly discovered edges. |
|
ARM3D: Attention-based relation module for indoor 3D object detection
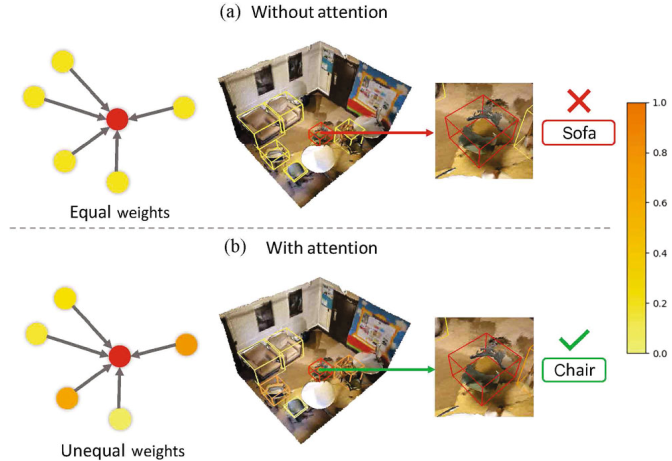
Yuqing Lan, Yao Duan, Chenyi Liu, Chenyang Zhu, Yueshan Xiong, Hui Huang, Kai Xu Computational Visual Media (CVMJ), 2022 Code / Paper ARM3D is a 3D object detection model that exploits contextual relationships to enhance 3D object understanding. |
|
DisARM: Displacement aware relation module for 3D detection
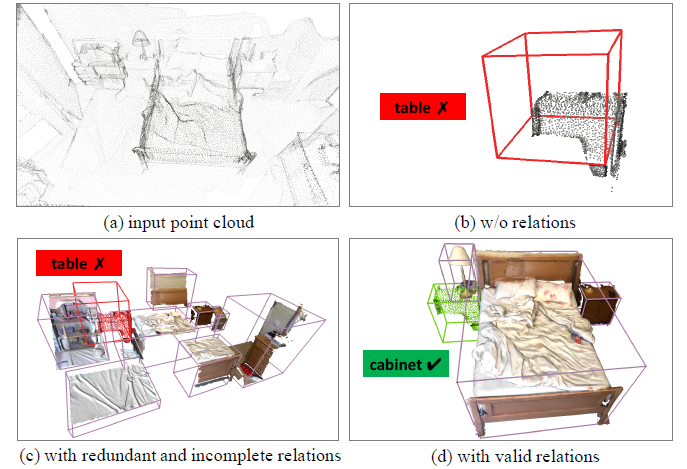
Yao Duan, Chenyang Zhu,Yuqing Lan, Renjiao Yi, Xingwang Liu, Kai Xu CVPR, 2022 Code / Paper The core idea of DisARM is that contextual information is critical to tell the difference between different objects when the instance geometry is incomplete or featureless. We find that relations between proposals provide a good representation to describe the context. |
|
3DRM: Pair-wise relation module for 3D object detection
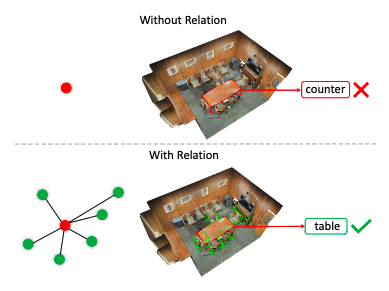
Yuqing Lan, Yao Duan, Chenyang Zhu, Yifei Shi, Hui Huang, Kai Xu Computers & Graphics, 2021 Code / Paper 3DRM is a relation module that improves the accuracy and robustness of 3D object detection by explicitly modeling the semantic and spatial relationships between objects for enhanced contextual reasoning. |
Miscellanea |
Academic Service |
The Visual Computer Reviewer
Scientific Reports Reviewer Machine Vision and Applications Reviewer Computer Graphics Teaching Assistant |
|
|